 Finding and Fixing Vulnerabilities Using AI
A key aspect of secure-by-design is hardening, that is, modifying the system/software so that defects are systematically unlikely to be exploitable or have more limited impact. As much as practical, apply hardening.
Defects are inevitable, but they do not necessarily need to be vulnerabilities. If vulnerabilities do exist, it’s best to constrain the likelihood of their exploitation and their impact as much as practical. The goal is to make it difficult for an attacker to exploit a defect, preventing defects from becoming serious vulnerabilities.
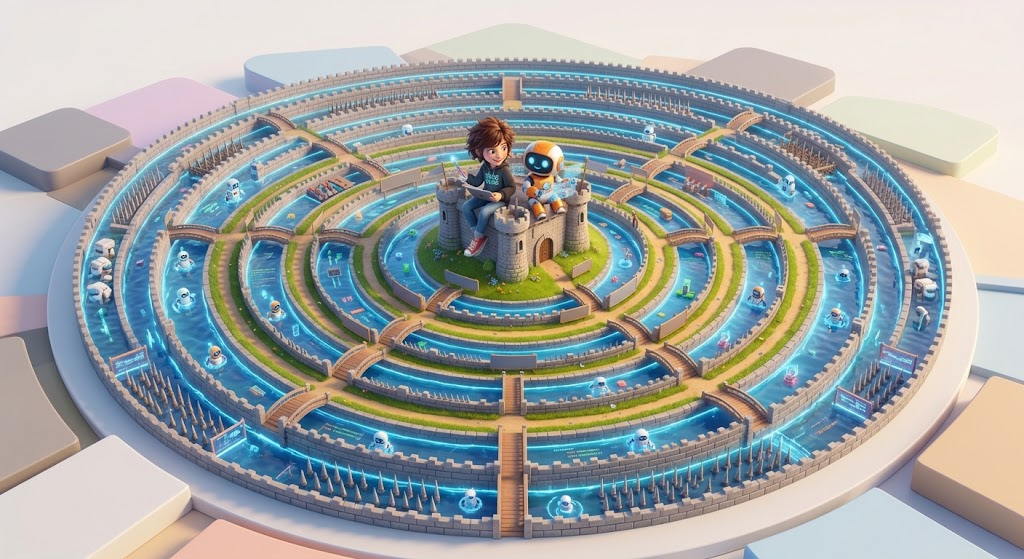
Apply hardening, using as many different techniques as make sense in your situation.
Some hardening measures are well-known industry-wide. For example, some languages are “memory-unsafe”, primarily C and C++. A memory-unsafe language does not, by default, protect against common memory errors such as reading or writing an array out of bounds. As a result, both humans and AI tend to produce more vulnerabilities in these languages. They’re also more difficult to analyze later, leading to more false positives [Bourzikas2026]. There are hardening approaches for this situation:
Other software hardening measures are specific to a particular program, developed after examining lessons learned from that software. Mozilla reported that “in recent years we received several clever reports from security researchers that managed to escape the process sandbox by triggering prototype pollution in the privileged parent process. Rather than fixing these problems one-by-one, we made an architectural change to freeze these prototypes by default. While auditing logs from the harness, we saw many attempts to pursue this line of escape that were thwarted by this design” [Grinstead2026-05].
Hardening works. Many well-run projects report that hardening measures do counter attackers, including powerful AI models. Mozilla reported that “just as interesting as what the models found is what they didn’t find — not because they didn’t try, but because they were unable to circumvent Firefox’s layered defenses.” [Grinstead2026-05] Similarly, Anthropic reported that Mythos Preview identified many areas of the Linux kernel that appeared to be vulnerabilities, yet “because of the Linux kernel’s defense in depth measures Mythos Preview was unable to successfully exploit any of these.” [Carlini2026]
It’s always been good practice to harden software or systems; however, AI has made it even more important, as hardening can sometimes counter chaining.
Chaining refers to the ability of modern AI systems to combine multiple defects into an exploitable vulnerability. Skilled human attackers have long been able to do this, but the ability of AI systems to chain multiple defects into an attack makes chained attacks much cheaper and easier to execute.
However, not all hardening measures are as effective against chaining. There are different kinds of hardening, reliable and unreliable:
Both kinds can counter attackers who don’t use AI. In many cases, a human attacker may decide that the second kind isn’t worth the effort. However, modern AI dramatically reduces the effort required to carry out certain types of attacks.
Anthropic reported that, “We have nearly a dozen examples of Mythos Preview successfully chaining together two, three, and sometimes four vulnerabilities in order to construct a functional exploit on the Linux kernel… [modern AI requires rethinking of] measures that make exploitation tedious, rather than impossible. When run at large scale, language models grind through these tedious steps quickly. Mitigations whose security value comes primarily from friction rather than hard barriers… become considerably weaker against model-assisted adversaries” [Carlini2026]. This ability to chain defects together often defeats the “somewhat more difficult” hardening measures.
Do use reliable hardening measures, that is, mechanisms that always counter certain kinds of defects:
However, unreliable hardening mechanisms (mechanisms that merely make a defect “slightly more difficult” to exploit) are much weaker against AI. For example, “modern browsers run JavaScript through a Just-In-Time (JIT) compiler that generates machine code on the fly. This makes the memory layout dynamic and unpredictable [so that exploiting the vulnerabilities is more difficult for humans, yet] Mythos Preview fully autonomously discovered the necessary read and write primitives, and then chained them together to form a JIT heap spray [exploitation]” [Carlini2026]. These layout variations weren’t designed to counter attacks, but historically they protected systems anyway, because it was too much effort for most human attackers to counteract the variations enough to form an attack. However, an AI can determine the layout cheaply enough that these kinds of attacks can become practical.
Address space layout randomization (ASLR) is an interesting illustration of the difference between reliable and unreliable hardening measures. ASLR is a reliable measure only if (1) there are enough randomization bits that brute-force guessing is impractical for performing an attack, and (2) there’s no way for an attacker to reveal data that would enable them to speed the attack beyond a brute-force attack. Unfortunately, it’s often possible for attackers to obtain data that reveals the random value. If an attacker can determine the random value, then once again AI can chain attacks. We recommend continuing to use ASLR, as it’s usually an easily-enabled defense. However, because ASLR is quietly broken if an attacker can determine its random value, and attackers can often obtain this value, don’t count on ASLR alone as a defense.
Hardening still matters, but you need to use reliable hardening mechanisms.
Where sensible, try to disable a system’s hardening mechanisms when trying to find and fix vulnerabilities in that system. This helps implement “defense in depth” where practical.
The system should be designed so that, where practical, an attacker must defeat multiple mechanisms to exploit the system. If the AI system is asked to evaluate the system only with all its hardening mechanisms in place, it will often not report cases where a single hardening mechanism alone prevented an attack.
For example, in one analysis of Mozilla’s Firefox, their testing environment “intentionally removed some of the security features found in modern browsers. This includes, most importantly, the sandbox, the purpose of which is to reduce the impact of these types of vulnerabilities” [Anthropic2026-03]. In this weakened environment, the AI “is tasked with developing an exploit” [Anthropic2026-04s].
In addition, have the AI look for defects in the hardening mechanisms themselves, such as looking for a “sandbox escape”. The goal is to allow the model to craft an attack that the hardening mechanism should prevent, and ensure that the hardening mechanism works against active attacks. This kind of evaluation was also done with Mozilla Firefox, where the AI was “permitted to patch the Firefox source code, so long as the modified code is restricted to run only in the sandboxed process. Such bugs are notoriously difficult to find with fuzzing… AI analysis provides much more comprehensive coverage of this critical surface” [Grinstead2026-05].
Evaluate the system without its hardening mechanisms, and separately evaluate the hardening mechanisms themselves, to try to improve them both. If you improve both, the result is much stronger defense-in-depth. The goal is a system in which attackers often must break multiple mechanisms to succeed.
Organizations need to focus on security basics and harden their organization’s environment and infrastructure. What organizations must do isn’t new, but it now has a new sense of urgency.
Several government cybersecurity agencies recommended the following practical actions:
Similarly, the UK NCSC recommends that organizations “put in place a policy to ‘update by default’ where you always apply software updates as soon as possible, and ideally automatically”. Where organizations can’t update everything, “they should prioritise applying updates to their external attack surfaces” [Whitehouse2026]. It’s true that “update by default” is a risk; the update may break functionality, or an attacker may subvert an update or the update process. However, the risk from failing to update is usually far greater.
The CSA notes that the basics still matter: “segmentation, egress filtering, multifactor authentication, and defense-in-depth/breadth all increase the difficulty for attackers… the basics remain valid and can be prioritized for risks that can’t be easily mitigated. Implement egress filtering (it blocked every public Log4j exploit). Enforce deep segmentation and zero trust where possible. Lock down your dependency chain. Mandate phishing-resistant MFA for all privileged accounts. Every boundary increases attacker cost” [CSA2026]. It adds that “[minimizing] base operating system images, or replacing third-party libraries with framework primitives as they emerge over time” can reduce an organization’s attack surface, and that AI can help do this [CSA2026]. Many recommendations focus on identity. CrowdStrike reports, “identity sits at the center of this problem. Many successful attacks do not end with the initial exploit. They become dangerous when they allow an adversary to assume a trusted identity, obtain credentials, or abuse excessive privileges. … [Prevention] includes enforcing zero standing privileges, continuously verifying access, limiting credential exposure, and connecting identity posture to endpoint and workload context in Real-time.” [CrowdStrike2026-FiveSteps]
Attackers may still manage to slip in. Logging/internal telemetry, offline backups, and having a Continuity of Operations Plan (COOP) are as vital as ever.
Resilience is no longer optional. CrowdStrike states that cyber resilience is becoming foundational. “As exploitation windows shrink, rapid recovery, low-disruption patching, and containment without business interruption become core defensive requirements. In a frontier AI threat model, resiliency is no longer a differentiator layered on top of prevention. It is part of prevention.” [CrowdStrike2026-FiveSteps]
All of this requires continuously testing organizations’ security assumptions. “Controls that look strong on paper may fail in practice. Segmentation may not be enforced consistently. Privileged access may be broader than expected. Exposure management must become dynamic, evidence-based, and specific to the environment.” [CrowdStrike2026-FiveSteps]
However, there’s no need to panic. All of this was true before AI; it’s simply more important to execute. What’s more, even the most advanced AI models cannot simply create vulnerabilities where none exist. As Red Hat’s Gunnar Hellekson notes, “context renders many bugs useless [and] some ‘vulnerabilities’ identified by AI are actually functionality bugs with no meaningful exploit path. Many issues [are low risk] because the affected [components are rarely exposed to the internet].” [Hellekson2026] In short, AI may find many “vulnerabilities” as defined by some document, yet many won’t be significant in your context. Act promptly on the ones that are.
Q1. Why does the material say hardening that only makes exploitation “somewhat more difficult” is weaker against modern AI attackers?
Q1. Why does the material recommend disabling hardening mechanisms during some evaluation runs?